


















Qwen4-Max is Alibaba’s new flagship model, released on November 16, 2026. It also runs on a new architecture built for long-running agents and professional work.
Its backbone holds 2.4 trillion parameters. However, only 71 billion are activated per token, so each response stays efficient.
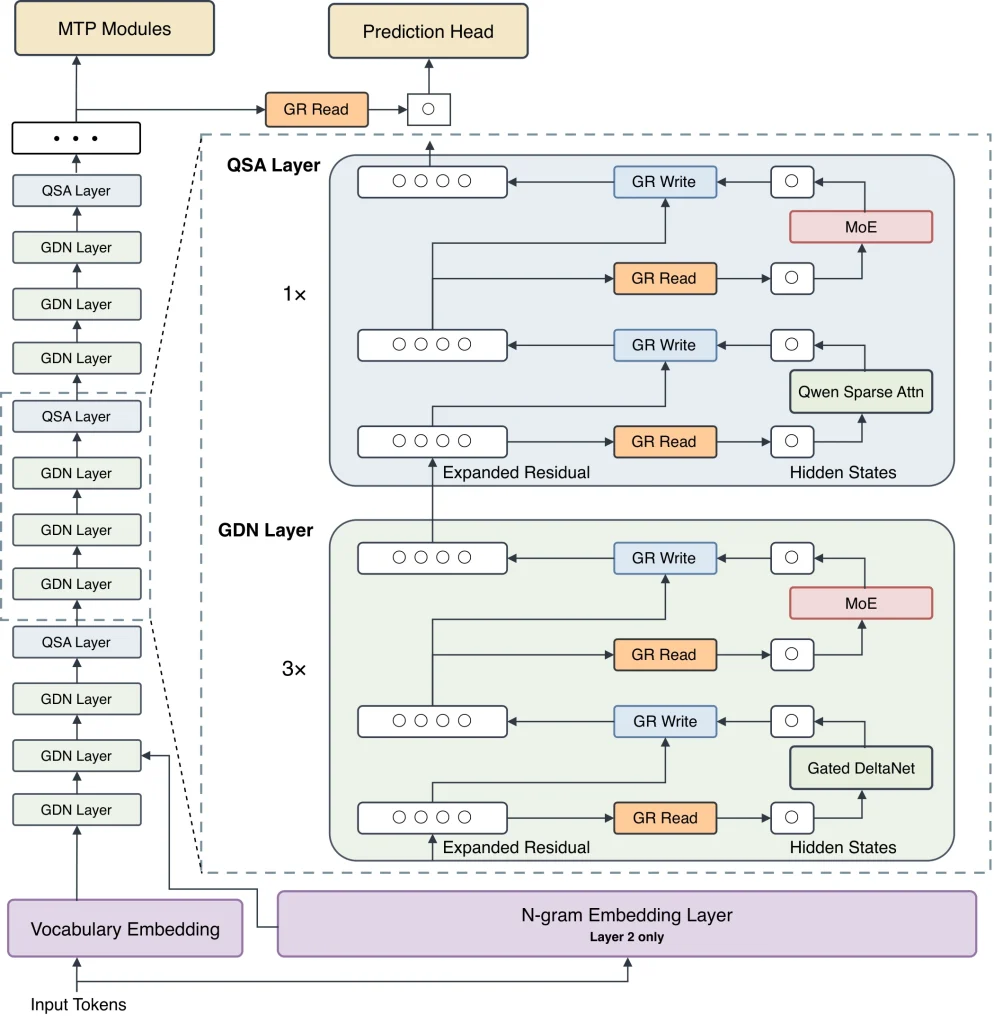
Image source: Qwen.ai
What Is Qwen4-Max?
Qwen4-Max is the first model in the Qwen4 series. In fact, Qwen describes it as a teammate for work, creativity, and discovery.
It uses a sparse mixture-of-experts design, so a router picks only about 71 billion parameters for each token.
In addition, the model carries 328 billion N-gram Embedding parameters. They represent common phrases and local patterns directly, although they sit outside the 2.4 trillion backbone.
Qwen4-Max also has native vision. Therefore, it accepts text, images, video, and PDFs, although it outputs mainly text.
Meanwhile, the attention stack mixes Gated DeltaNet layers with Qwen Sparse Attention. Because they pick relevant context in blocks, long inputs cost less to process.
A One-Million-Token Context Window
The context window holds 1 million tokens. That budget also covers input and output together.
In practice, the maximum input is about 991,808 tokens without thinking. With thinking on, however, it’s about 983,616.
Output also has its own cap. Specifically, it’s 131,072 tokens without thinking, and 262,144 for reasoning plus answer.
In other words, the window is a shared budget, not one million tokens of input plus a separate output.
Built for Creative and Professional Work
Qwen positions Qwen4-Max as built for work, so its showcase spans coding, law, healthcare, research, gaming, manufacturing, and 3D design.
To support this, Qwen built the Work360 benchmark, whose taxonomy covers 26 top-level domains, 182 subdomains, and 721 specialized fields.
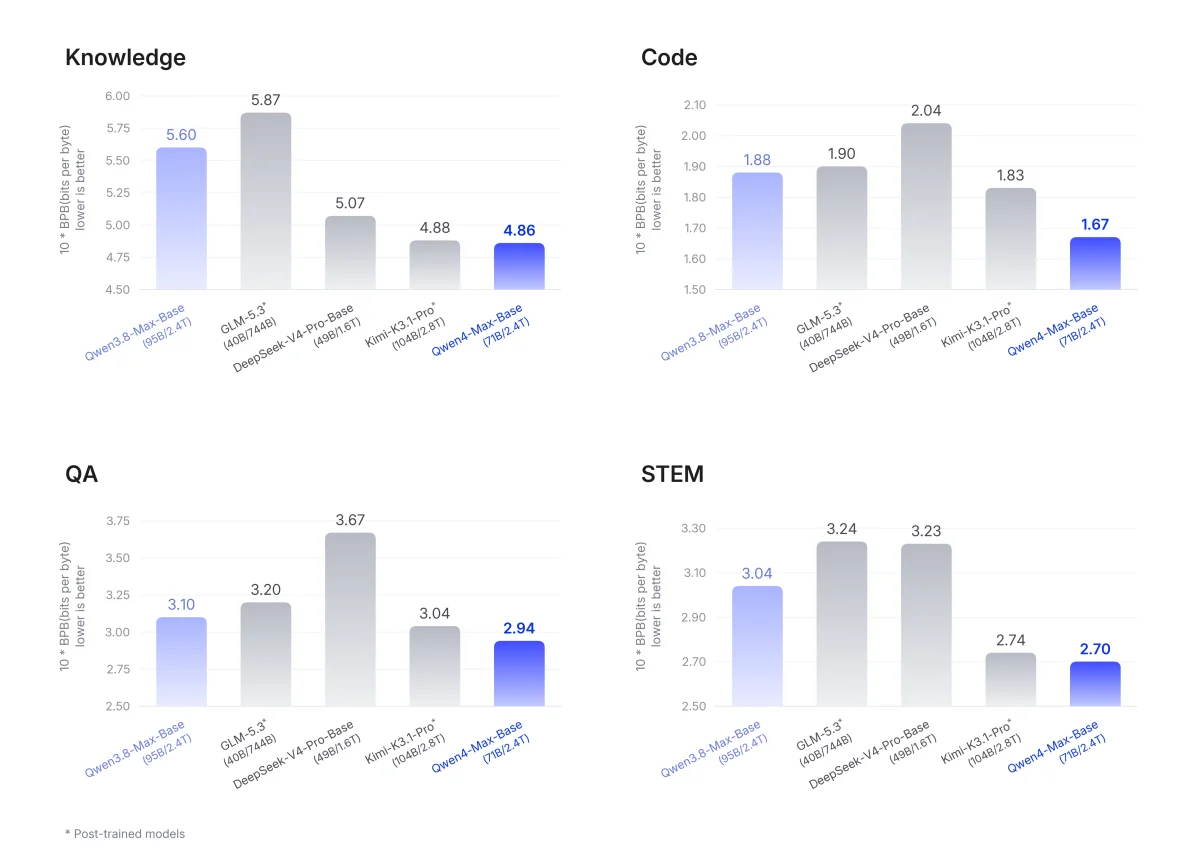
Image source: Qwen.ai
On Work360, Qwen4-Max scores 52.69, while Qwen3.8-Max scores 47.74. Consequently, Qwen calls it a substantial step over the previous generation.
Qwen also showed several demos. For example:
- 3D and game development — the model operates Blender, Unreal Engine, Unity, and Godot to build 3D assets and scenes. Moreover, it generated an installable Android racing game from a plain-language brief.
- Precision manufacturing — an agent read part drawings and produced machining programs, so a task of about 475 minutes finished in 24.
- Scientific discovery — one demo ran for 48 hours designing candidate coolant molecules, while another made 454 tool calls screening Alzheimer’s drug candidates.
- Law and healthcare — it turned 198 disorganized documents into an 86-page due diligence report. Likewise, it analyzed 1,433 images from patient records and drafted four care recommendations.
However, these are officially selected demonstrations, not large-scale success-rate tests. Therefore, scientific and medical outputs still need experimental and clinical validation.
Token Efficiency and Cost
Qwen4-Max completes tasks with fewer tokens than Qwen3.8-Max, so cost per task falls sharply.
| Benchmark | Reasoning effort | Token usage drop |
|---|---|---|
| Work360 | Xhigh | About 24% |
| Work360 | High | About 35% |
| Terminal-Bench 4.0 | Xhigh | About 48% |
| Terminal-Bench 4.0 | High | About 49% |
Qwen says the model picks tools and solution paths faster, so it wastes fewer tokens on redundant searches and repeated file reads.
Pricing also fell. For instance, QwenCloud lists $1.50 per million input tokens and $4.50 per million output tokens, while cached input costs $0.075.
That’s also 25% below Qwen3.8-Max’s list price. As a result, the average Work360 task cost drops from $4.43 to $1.67. In other words, that’s a 62% reduction.
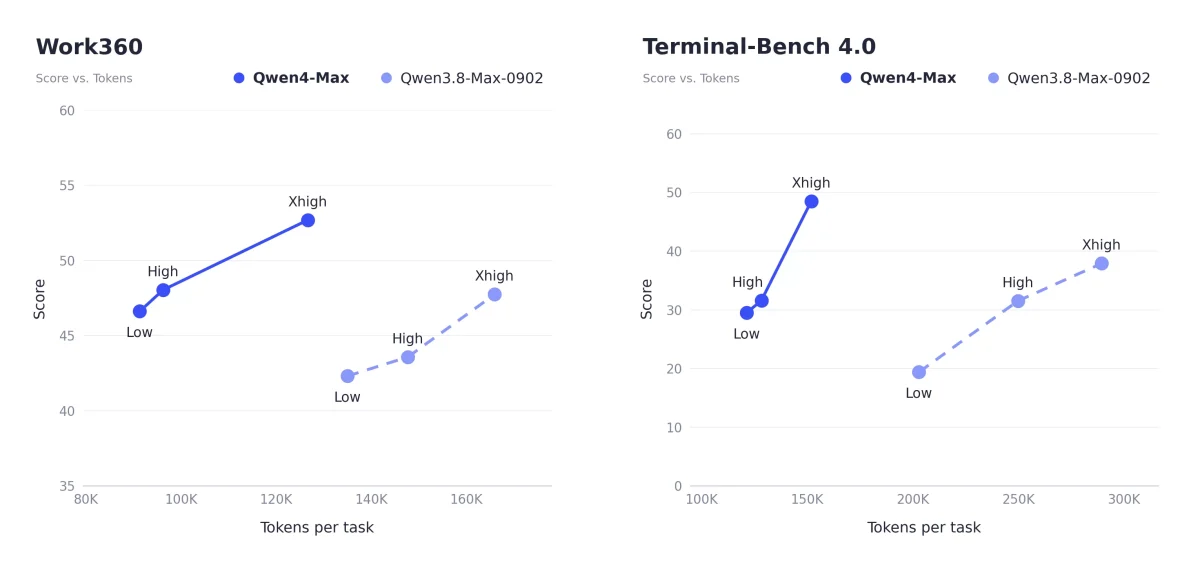
Image source: Qwen.ai
However, this is Qwen’s number on Qwen’s own benchmark. Short Q&A, uncached tasks, and heavy reasoning may also differ.
For comparison, Artificial Analysis measured $3.27 per task on its own index, although that’s a different workload.
How Qwen4-Max Performs on Public Benchmarks
Qwen published 16 public benchmarks, and overall, Qwen4-Max beats Qwen3.8-Max on all 15 where both have scores. Furthermore, it holds the top score on four.
| Benchmark | Qwen4-Max | Best score in Qwen’s chart |
|---|---|---|
| DeepSWE v1.1 (agentic coding) | 75.7 | Qwen4-Max |
| Agents’ Last Exam | 46.7 | Qwen4-Max |
| BioMysteryBench | 85.0 | Qwen4-Max |
| HLAB-Vals (legal agents) | 21.3 | Qwen4-Max |
| Terminal-Bench 4.0 | 48.5 | Kimi K3.1 (67.2) |
| ProgramBench | 31.5 | Claude Opus 5.5 (65.0) |
Still, gaps remain. Terminal coding, software replication, and chart understanding also trail the leaders. Likewise, against Claude Opus 5.5, it records 6 wins and 10 losses.
In short, Qwen4-Max is highly competitive in law, bioinformatics, and long professional agent tasks. But it doesn’t lead everywhere.
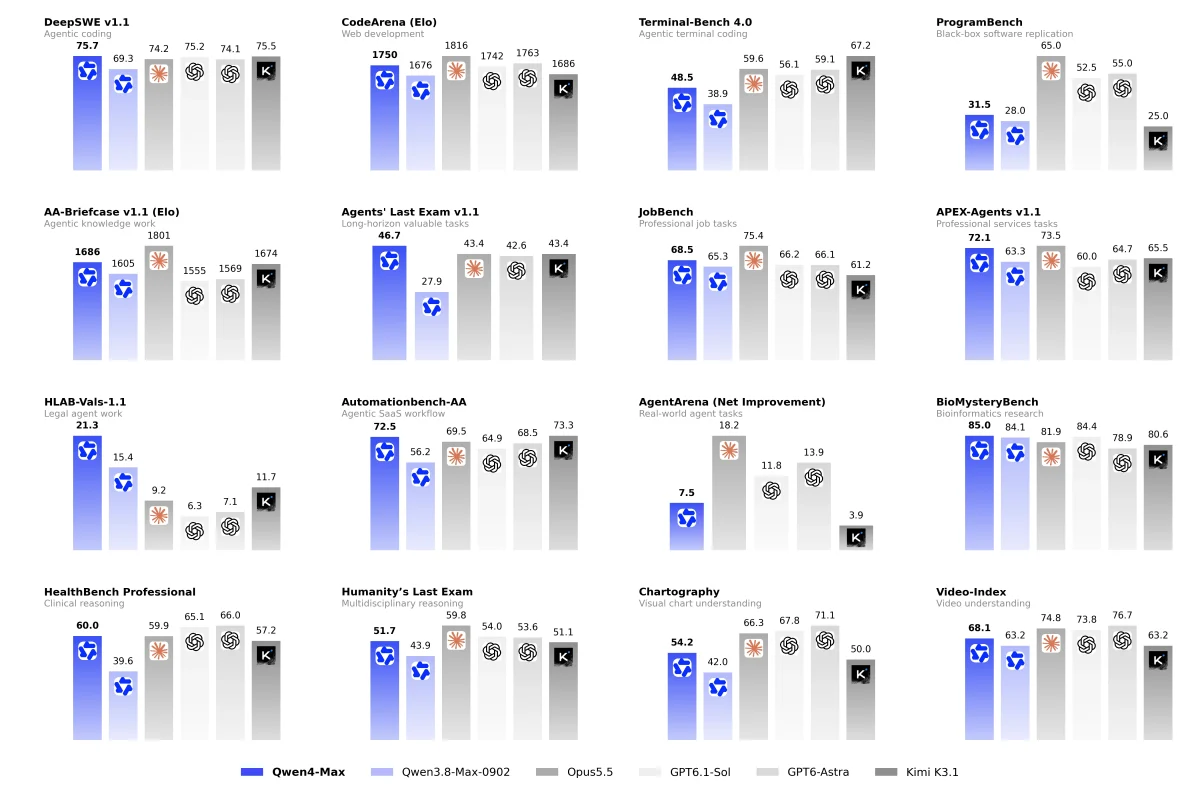
Image source: Qwen.ai
Access and Availability
Qwen4-Max is a proprietary model, so Alibaba hasn’t released downloadable weights.
Instead, you can reach it through the QwenCloud API, Token Plan, QwenWork, Qoder, and QwenStudio. Notably, the API works with OpenAI Chat Completions, Responses, and Anthropic Messages formats.
Additionally, it supports tool calling, structured output, and prompt caching. Meanwhile, Qwen says smaller Qwen4 models will be open-sourced later, but it hasn’t shared dates.
Broader Implications of Qwen4-Max
Qwen4-Max also points toward a few larger shifts in how labs build and sell models:
- Efficiency as a headline metric — for agent workloads, this matters because fewer tokens per task counts as much as a higher score.
- Capacity without extra compute — because N-gram Embeddings add stored knowledge, per-token computation stays low.
- From chatbot to coworker — Qwen frames the model around whole workflows instead of chat, including reading materials, operating software, and delivering files.
Conclusion
Qwen4-Max pairs a huge 2.4T backbone with a small 71B active footprint, while also adding a million-token context and strong work-focused skills.
Its biggest claim is efficiency, because it promises fewer tokens, lower prices, and a 62% lower task cost on Qwen’s benchmark. Ultimately, test it on your own workloads before you commit.
Ready to bring intelligent AI capabilities closer to your users? Your journey starts at Webkul.

Be the first to comment.