Desert Ant Labs: Exploring the Future of On-Device AI
On-device AI runs specialized models directly on a user’s device instead of sending every request to the cloud.
Cloud-based AI offers powerful models but introduces latency, infrastructure costs, privacy concerns, and internet dependency.
Desert Ant Labs, a European AI lab, explores this approach by building small, efficient models for local inference.
What Is Desert Ant Labs?
Desert Ant Labs develops specialized on-device AI models for audio, text, and vision tasks.
Its goal is to make AI inference fast enough to run directly on devices such as smartphones, laptops, and desktops.
The company currently offers 18 models, including 12 available models and 6 beta models.
Rather than creating one model that tries to handle everything, Desert Ant follows a focused approach. Each model targets a specific task.
For example, Voz handles speech recognition, while Clear focuses on speech enhancement. Redact detects and masks personally identifiable information (PII), whereas Tongue identifies languages.
The ecosystem also includes models such as Gist for topic tagging and Shapes for recognizing simple drawn shapes. Meanwhile, Face focuses on on-device face matching and is currently available in beta.
Desert Ant also provides SDKs for Swift, Kotlin, and JavaScript.
Therefore, developers can integrate its models into applications across different platforms without creating their own inference infrastructure.

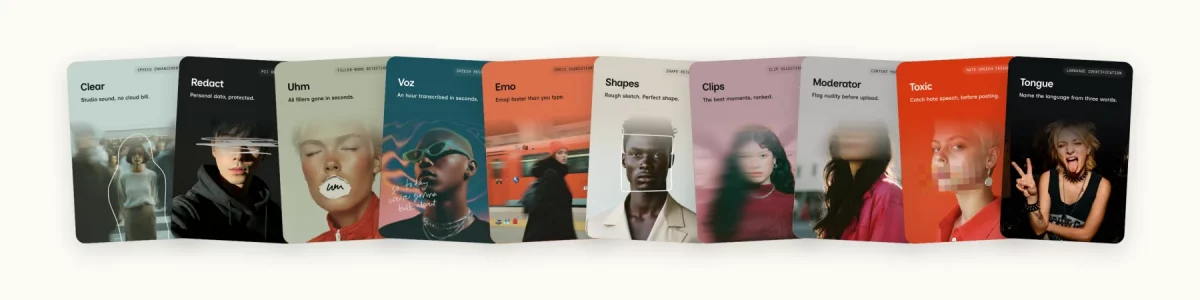
Image Source: Desert Ant Labs
The Problem with Cloud-Based AI
Cloud-based AI has made advanced capabilities easier to integrate. However, it is not always the most efficient solution for every task.
Consider a voice application. It may need to enhance audio, detect filler words, identify a language, or transcribe speech.
Sending each operation to a cloud service adds network communication to the workflow.
First, this communication introduces latency. The application must upload the data, wait for inference, and download the result.
Second, frequent cloud inference increases infrastructure costs. An application that performs AI processing on every interaction can generate a large number of API calls.
Privacy creates another challenge. Applications may process private messages, recorded conversations, faces, or personal information.
In many cases, these tasks do not require the data to leave the device.
More importantly, many AI features have clear and limited objectives.
A messaging application might only need to detect PII. A voice recorder might only need noise reduction. A camera application might only need to identify a particular visual pattern.
These tasks do not necessarily require a large general-purpose AI model.
That raises an important engineering question:
If a task has a clearly defined purpose, why send it to a large model in the cloud?
The Solution: Specialized AI on the Device
Desert Ant Labs approaches this problem with a “one model, one task” philosophy.
Instead of using a large model for every operation, developers can select a smaller model that matches the specific requirement. The application can then perform inference directly on the device.
This architecture offers several advantages.
Lower Latency
Local inference removes the network round trip. Therefore, applications can respond without waiting for a remote server.
For example, Desert Ant reports that Voz can transcribe 10 minutes of audio in about two seconds on an iPhone. The company also reports a 4.7× speed advantage over Whisper in its stated comparison.
Better Privacy
On-device AI can keep sensitive information local.
For example, Redact can identify and mask PII before an application sends other information to a server.
Similarly, Desert Ant describes its Face model as performing face matching without sending images away from the device.
This approach can reduce the amount of sensitive data that applications need to transmit.
Lower Infrastructure Costs
Local inference also reduces dependence on cloud inference services.
Instead of paying for every AI operation on a remote server, an application can perform suitable tasks using the device’s own computing resources.
Desert Ant currently offers its models free for up to 100,000 monthly active devices per SDK, with unlimited inference per user.
Task-Specific Optimization
Specialization allows developers to use models designed around a narrow objective.
For example, Tongue identifies languages across 84 languages using a model of around 2 MB.
A language-identification task does not need the reasoning capabilities of a large language model. A small model can handle the job with a much smaller resource footprint.
The principle is therefore not simply about making AI smaller.
Instead, it asks:
What is the smallest model that can solve this task effectively?
How On-Device AI Can Work with Cloud AI
On-device AI does not have to replace cloud AI.
Instead, the two approaches can complement each other.
Consider an AI-powered note-taking application.
A user records a meeting. The application could first process the recording locally. A speech-enhancement model could remove background noise.
A speech-recognition model could then generate a transcript. Another local model could identify the language or detect sensitive information.
Only after these local operations could the application send the relevant information to a larger cloud model for summarization or deeper reasoning.
The architecture could look like this:
User Input → On-Device AI → Simple Task? → Local Result
↓
Complex Reasoning Required → Cloud AI → Final Result
This approach keeps frequent and well-defined operations local. At the same time, it preserves access to powerful cloud models when the application needs deeper reasoning.
Desert Ant Labs describes a similar idea through its “cerebellum” concept. Small local models handle fast and frequent tasks, while larger models can take over more complex reasoning.
As a result, developers do not have to treat cloud and on-device AI as competing technologies. They can assign each task to the architecture that fits it best.
Where On-Device AI Makes Sense
This approach works particularly well when an application needs fast, repetitive, or privacy-sensitive inference.
For example:
- Voice applications: Enhance audio, detect filler words, and transcribe speech locally.
- Messaging applications: Detect and redact PII before data leaves the device.
- Note-taking applications: Identify languages and classify topics locally.
- Camera applications: Perform selected visual analysis without uploading every frame.
- Creative applications: Process audio or other media without requiring constant cloud connectivity.
The common factor is a well-defined task.
A specialized model does not need to understand everything. It only needs to perform its specific job efficiently.
Conclusion
AI development has traditionally focused on building larger and more capable models. However, on-device AI presents another path.
Many everyday AI features have limited and clearly defined requirements. Therefore, they do not always need a large model running on a remote server.
Desert Ant Labs demonstrates this approach through specialized models for speech, audio, text, and vision.
Its models target individual tasks such as transcription, speech enhancement, language identification, PII detection, and face matching.
The biggest opportunity may not come from choosing between local AI and cloud AI.
Instead, it may come from combining them intelligently.
Small models can handle fast, repetitive, and privacy-sensitive operations on the device. Larger models can then handle complex reasoning when required.
Ultimately, on-device AI changes an important assumption in AI application development: not every intelligent operation needs to leave the device.
Ready to bring intelligent AI capabilities closer to your users? Your journey starts at Webkul.